How Andy Denning decides which A/B tests are worth running

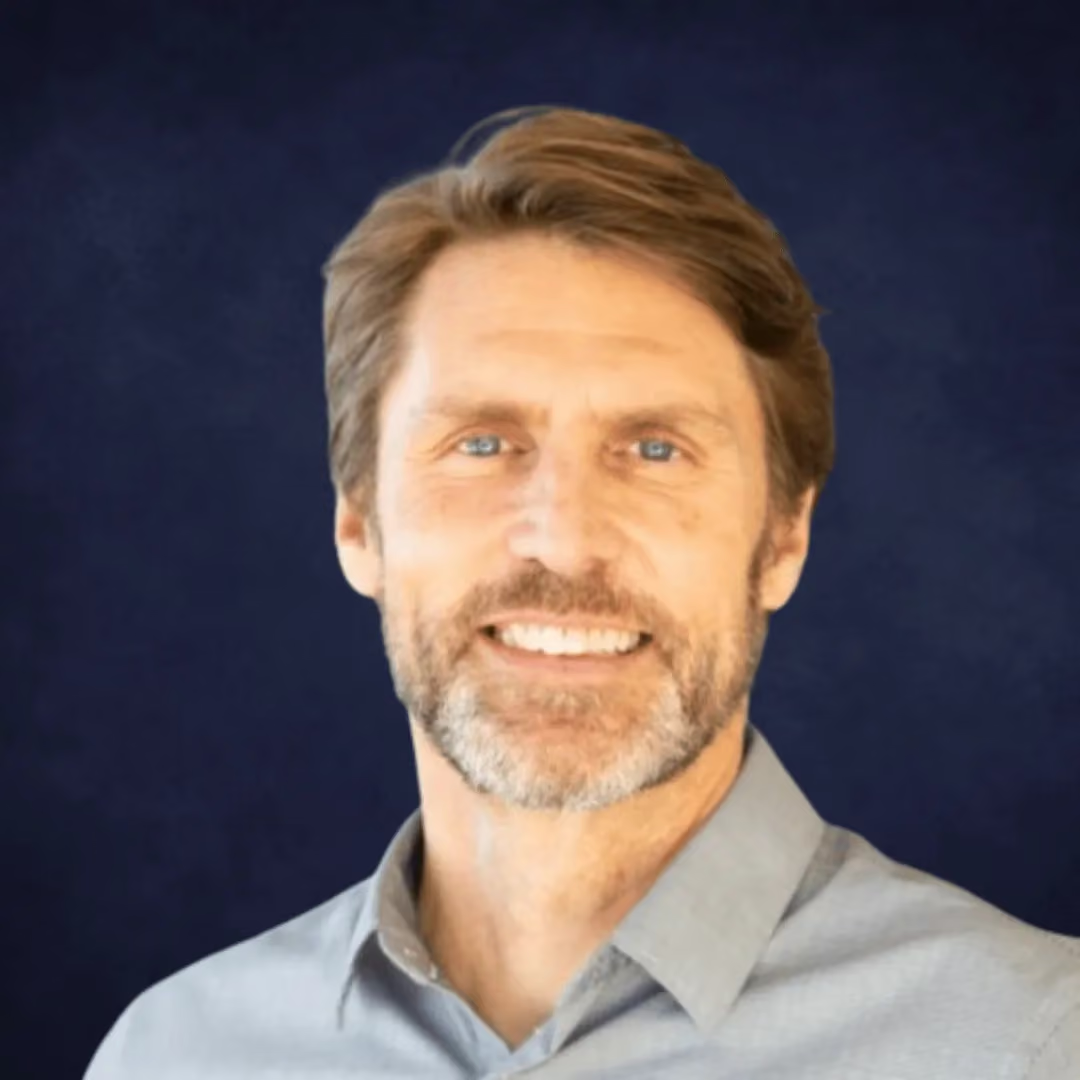
Most experimentation programs measure themselves by how many tests they run. Andy Denning, Product Leader, thinks that is the wrong scoreboard. On this episode of The Experimentation Edge, he told host Ashley Stirrup that the decision about what to test matters more than the test itself.
A smaller team with big decisions
Andy’s experience includes a two-sided jobs marketplace that has operated for about 25 years. It is a two-sided marketplace: job seekers search and apply for roles, and recruiters, agencies and direct employers post jobs and look for candidates. It is mainly a UK business, and in the last few years it has pushed into the US.
Andy says the business operates around number three in its market with a much smaller organization than its competitors. That raises the stakes. "The decisions that we make are probably even more important because of our resources," he said. The business has a big appetite to test and learn, so his focus has been on which decisions are worth testing, which are worth learning from, and which can simply be built.
Why more tests can mean less truth
Andy sees the industry leaning toward test velocity, on the idea that more experiments mean more learning. The risk is in the quality. "Underpowered tests, badly chosen tests actually can manufacture a false confidence in things which often can be worse than actually running nothing," he said.
For Andy, experimentation is also a tool for organizational honesty. In smaller, fast-moving companies there are many opinions in the room. "Experimentation outside of tooling actually forces people to say what they believe before the data and holds them to it," he said. It moves teams away from decisions by opinion or by seniority.
When the organization started experimenting, setting up and running tests was not the problem. The gap was the feedback loop: taking what a test taught them and doing something with it, instead of treating it as a tick-box exercise.
Teams that own their tests
The organization uses value-stream-aligned, cross-functional teams that include product, engineering and design. Each team owns the experiments that test its hypotheses, and leans on the data team to check baselines and sample sizes against weekly traffic. With tools like PostHog doing much of the sizing and significance work, teams can run an experiment end to end with few dependencies.
To spread learning, Andy runs "popcorn sessions": the team watches session recordings from moderated and unmoderated tests together. "We'll put everyone in the room just to watch these recordings because it creates a closeness to the customer," he said. His next step is to bring sales, marketing and operations into experiment design earlier, not only into the results.
The branding test that didn't move applications
In the US, the business was a little-known brand, and early conversion was weak. Many US job seekers jump through several sites before they reach an application, and Andy's team believed they did not trust who they were really applying to. So they used their headless CMS to brand the registration and apply flow with the hiring company's brand, and ran the test in about a week.
The result: little to no impact, and in some cases a negative one. Surveys pointed to a different answer. Job seekers wanted supplementary information on the listing, such as salary, culture and benefits.
Looking back, Andy says a judgment layer could have saved the test. The branding was a positive step they would likely have shipped anyway. "Would we do it anyway?" is a question to ask before you spend traffic. Ashley pushed back with Ronny Kohavi's Bing speed test as an example of how even an "obvious" change can teach you how much it matters. Andy agreed that there is always value in having a mechanism to run the test.
Start with the riskiest assumption
Andy's core advice on experiment design: "Identify the riskiest assumption you want to test, not the most comfortable one." It is tempting to test the safe thing because it is quick and gives a cleaner metric. But the question he asks his teams is, "How quickly and cheaply can you test the riskiest assumption? Because that's the thing that's load bearing."
He adds a few practical checks:
- Do you have a baseline to compare against?
- How long will the test take? If the numbers say 6 weeks, stop and find a different method.
- What can your population support? Direct-to-consumer has volume; B2B often does not.
- What are the non-goals? Naming what you won't test stops experiments from growing arms and legs.
- Always have a pivot point and a plan B.
AI raises the value of judgment
AI makes it possible to create almost endless variants at almost zero cost. Andy's warning: "It's very, very easy now to flood a backlog, to flood a roadmap with just low conviction tests because we can run them." Most companies are not running hundreds of experiments a day, even if AI makes them feel like they can.
The bottleneck has moved from creating experiments to the quality of the hypothesis and having enough traffic to get a clean read. "The ability to know the hypothesis, be confident about learning from it, matters far more now than it ever has," Andy said. Commoditized tools can push low-risk tests through quickly, while human judgment goes to the riskier bets.
The same shift is hitting hiring. AI tools have unleashed what Andy described as an "apply tsunami," leaving recruiters with thousands of applications per role. He expects the real opportunity to be in better assessment of both the role and the candidate, so employers can find the right person and defend their decisions.
Related articles


Ready to ship faster?
No credit card required. Start with feature flags, experimentation, and product analytics — free.